OmniPiano: Diverse Dexterous Piano-Playing Challenges for Standard, Robust, Safe, and Multi‑Agent RL

Anonymous Authors

Paper under double-blind review

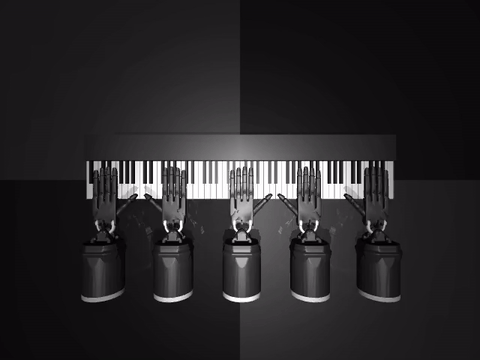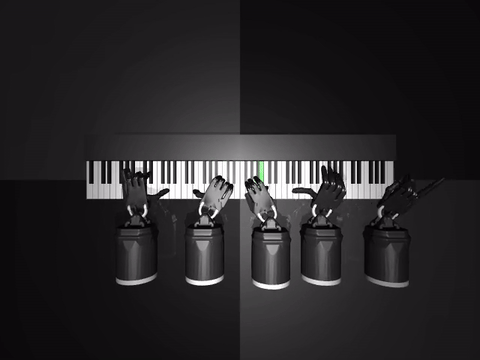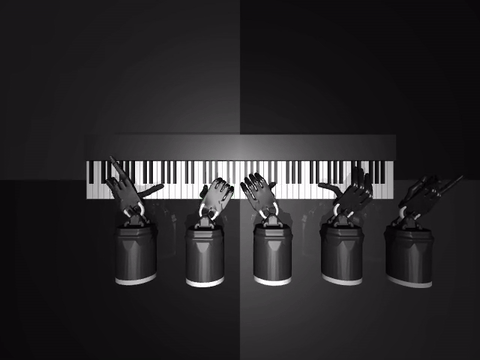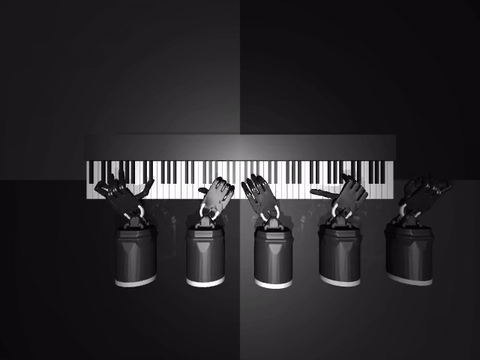
OmniPiano overview: four tracks — Standard, Robust, Safe, and Multi-Agent RL — built around a shared piano-playing core
Figure 1: Overview of OmniPiano Benchmark. A unified benchmark for learning dexterous multi-hand piano playing.
1–5Shadow Hands
111max action dims
150songs
912task settings
50baseline algorithms
4LLM-based agents

Abstract

Dexterous robotic manipulation remains a major challenge in robotics, exemplified by piano playing, which requires coordinated control of fingers and arms and provides a demanding testbed for reinforcement learning (RL). Although RoboPianist established a benchmark for robotic piano playing, it is restricted to two hands and does not support unified evaluation. To address this gap, we introduce OmniPiano, a benchmark that extends RoboPianist from one to up to five Shadow Hands and supports standard, robust, safe, and multi-agent RL within a shared piano-playing task family. OmniPiano is developed for scalable and diverse piano-playing tasks with configurable perturbations, explicit safety constraints, and decentralized cooperation settings. With at least 912 task settings and 50 baseline algorithms, OmniPiano also incorporates LLM-based agents to broaden the evaluation scope and reveal new empirical insights. Particularly, to facilitate usability and extendability, OmniPiano adopts a highly modular design and provides comprehensive tasks to support RL study of task performance, robustness, safety, and cooperation in dexterous control.

Why piano playing?

A precise, measurable testbed for dexterous control

A MIDI score specifies exactly which keys to press, hold, and release, and when. Comparing intended and actual key activations gives a concrete, note-level measure of how well an RL policy controls a high-dimensional, contact-rich body.

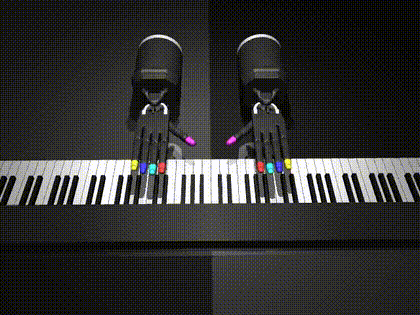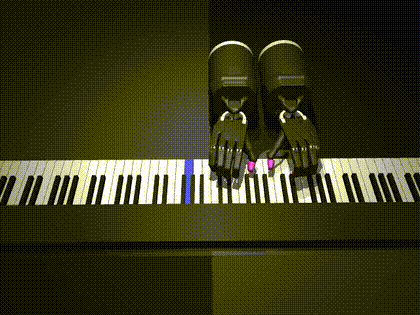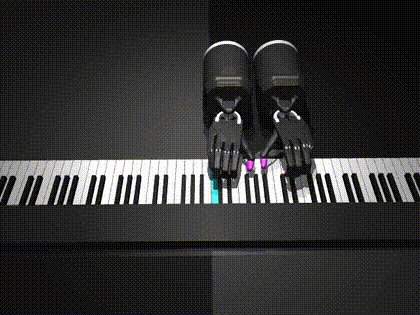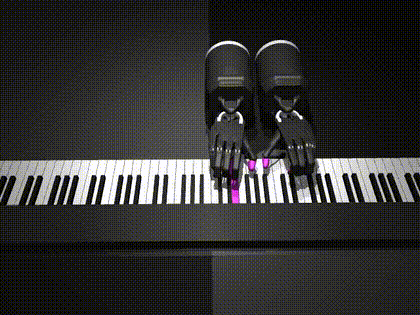
Two simulated Shadow Hands playing a piano keyboard
  1. High-dimensional continuous control

    Anthropomorphic Shadow Hands with position control on an 88-key piano: 44 DoF for two hands, scaling to 111 action dimensions with five hands.

  2. Spatial & temporal coordination

    Fingers on every hand must hit different notes at the right time, without colliding with each other in a shared workspace.

  3. Diverse task settings

    150 songs × 8 hand settings, with restricted or unrestricted hand mobility, plus perturbation, safety, and multi-agent variants of the same task.

One core task, four tracks

Vary one factor at a time

Rather than combining every factor in a single environment, OmniPiano keeps the core piano-playing task fixed and varies one aspect per track, so performance differences can be attributed to a single design choice. All tracks are exposed through consistent Gymnasium (single-agent) and PettingZoo (multi-agent) interfaces in MuJoCo, and work with Stable-Baselines3, RLlib, and TorchRL.

Comparison of OmniPiano with related reinforcement-learning benchmarks.
FeatureRoboPianistRobust-Gym.Safety-Gym.OmniPiano
Action dimension451–302–1723–111
Episode horizon240–371050–1600500–1000240–3710
Dexterous piano playing
Robust RL track
Safe RL track
Multi-agent RL track
Unified task setting
LLM-agent evaluation
01

Standard RL

How well can a policy play, as repertoire and the number of hands grow?

Hand settings. Eight hand settings from one to five Shadow Hands. Unrestricted hands move freely across the keyboard; restricted hands are each confined to a fixed region, which keeps exploration and credit assignment tractable as the number of hands grows.

Reward. Following RoboPianist, rt = rtkey + rtmatch − λenergy rtenergy, rewarding correct key presses, fingertip-to-key proximity, and low actuation. Two variants: a fingering-annotated reward, and an optimal-transport reward that needs no fingering annotations and so supports arbitrary MIDI files and hand configurations.

Baselines. PPO, SAC, CrossQ, TD3, TQC, and four LLM-based agents that optimize keyframes over ten iterations.

Results

Radar charts of F1 score for PPO, SAC, DeepSeek-V4.1-Flash and GPT-6 Astra across eight hand settings on three songs
Figure 5: F1-score comparison of PPO, SAC, DeepSeek-V4.1-Flash, and GPT-6 Astra across eight hand settings (U = unrestricted, R = restricted) on three piano pieces of increasing difficulty.
F1 of LLM agents over ten optimization attempts compared with RL methods over 5M steps
Figure 6: F1 of LLM agents over ten keyframe-optimization iterations, and of RL methods over 5M steps, for the two-hand setting on three pieces.

Takeaway. RL methods improve F1 more steadily, while LLM-based agents show less consistent gains across attempts, but can outperform some RL baselines on certain pieces, especially with more hands. Restricting hand mobility makes learning easier.

More results: restricted vs. unrestricted hands
Evaluation reward for PPO and SAC under restricted and unrestricted configurations
Figure 10: Periodic evaluation reward during training for PPO and SAC under restricted and unrestricted configurations across the three songs.
02

Robust RL

Does the playing hold up when signals and physics are perturbed?

Robust RL design: action, environment, reward and observation disruptors acting on the agent–environment loop
Figure 2: Robustness perturbations are introduced through four independent disruptors acting on the agent–environment interaction loop.

Signal perturbations

Operators Do, Da, Dr corrupt observations, actions (actuation uncertainty), and rewards during interaction.

Environment perturbations

De changes gravity, fingertip–key contact friction, and the initial pose of each hand, per episode or per step.

Composable

Gaussian, uniform, or shift noise at low / medium / high levels on any channel, combined freely to test isolated and compound effects.

Results

PPO evaluation reward under six perturbation channels and three noise families
Figure 7: Periodic evaluation reward of PPO across six robustness channels under Gaussian, uniform, and shift perturbations, with the clean environment shown as a reference.

Takeaway. Action and hand-position perturbations cause the largest performance drops. Action noise is more disruptive than observation or reward noise because it directly corrupts the executed commands.

More results: robust RL algorithms and composed perturbations
Cross-algorithm robustness under Gaussian action perturbations on Clair de Lune
Figure 11a: Cross-algorithm robustness (PPO, SAC, A2PSAC, SCPO, ERPO) on Clair de Lune under Gaussian action perturbations.
Cross-algorithm robustness under Gaussian reward perturbations on Clair de Lune
Figure 11b: The same comparison under Gaussian reward perturbations.
Composed Gaussian perturbations on Für Elise with three hands
Figure 12: Progressively composing observation, reward, action, gravity, and hand-pose perturbations on three-hand Für Elise.
03

Safe RL

Accurate playing is not the same as safe playing.

Safe RL design: four safety semantics combined with three cost settings
Figure 3: Four safety semantics specify the constrained behaviors, while Event, Fraction, and Excess provide alternative ways to quantify violations.

Safety semantics

  • Joint Range: keep selected joints within prescribed intervals
  • Actuator Power: limit instantaneous mechanical power
  • Injured Finger: extra limits on a designated finger
  • Hand Collision: limit contact forces between hands

Cost settings

  • Event: does a violation occur at this step?
  • Fraction: share of monitored elements over their limits
  • Excess: normalized deviation beyond the threshold

Reward and cost stay separate. Low cost achieved by simply not playing counts as a trivial-safe failure.

Results

Episode cost and evaluation reward on three-hand Pictures at an Exhibition with power-excess cost
Figure 8a: Three hands, Pictures at an Exhibition (Great Kiev), actuator-power excess cost. PPO, PPO-Lag, OnCRPO, CPO, and CUP; 5M steps, three seeds.

Takeaway. Unconstrained PPO earns the highest return, but its cost stays orders of magnitude above the budget. Constrained methods bring cost down toward the budget at the price of lower return, which makes the safety–performance trade-off explicit.

More results: a second piece
Episode cost and evaluation reward on three-hand Polonaise Op. 40 No. 1 with power-excess cost
Figure 8b: Three hands, Polonaise Op. 40 No. 1, actuator-power excess cost.
04

Multi-Agent RL

Split the hands across decentralized agents that share one musical goal.

Multi-agent RL design: base configuration and four SCHO variants
Figure 4: A typical four-hand example. Users can freely configure the MIDI score, number of hands and agents, hand-to-agent assignments, and each agent's observation and action ranges.

Scalability

How many agents control the same set of hands.

Coupling

How much agents' keyboard action ranges overlap.

Heterogeneity

Balanced vs. imbalanced hand assignments.

Observability

How much of the keyboard and teammates each agent sees.

Results

Team return of IPPO, MAPPO, HAPPO, A2PO and FACMAC across five cooperation settings
Figure 9: Task-wise training return of IPPO, MAPPO, HAPPO, A2PO, and FACMAC on four-hand Winter Wind across the Base task and four SCHO variants, with centralized PPO as a reference.

Takeaway. Scalability (one agent per hand) reaches the highest or near-highest return for every algorithm, while Coupling hurts most, with FACMAC the exception. Centralized PPO falls far behind, and IPPO remains a surprisingly strong baseline.

More results: team return and musical F1 per task
Detailed MARL results: team return and musical F1 per algorithm and task
Figure 20: Detailed MARL results. The first row compares task-wise team return per algorithm; the second and third rows compare team return and musical F1 across algorithms for each task.

Cross-benchmark insights

Five findings

1

Song duration alone does not explain difficulty

Longer songs are not necessarily harder. Note density (NPS) is a better indicator, and fingering complexity, hand coordination, and key transitions matter too.

2

More agents help when they reduce per-agent burden

Giving each agent a single hand achieves the highest or near-highest return: the lighter control load outweighs the extra coordination.

3

More hands do not guarantee better performance

Extra hands add control capacity but make learning harder. Scalability should reflect how well an algorithm exploits them.

4

Action and hand-position noise are most disruptive

They cause the largest drops, making actuation and hand initialization the key robustness challenges in dexterous piano playing.

5

Restricting mobility can simplify learning

Confining each hand to a region beats unrestricted motion despite a smaller reachable space: more freedom also means harder exploration.

Taken together

Evaluating dexterous control needs more than one task or configuration. Hand count, morphology, perturbation type, musical piece, and restriction setting each expose different capabilities and limits of current methods.

Rollouts

Videos

Five Shadow Hands playing piano in the restricted setting
StandardFive hands, restrictedEach hand confined to its own keyboard region
Video coming soon
StandardOne to five handsScaling the embodiment on the same piece
Video coming soon
StandardRL vs. LLM agentAn RL policy compared with an LLM-based agent
Video coming soon
RobustAction noiseClean vs. perturbed actuation
Video coming soon
RobustPhysical perturbationsGravity, contact friction, and initial hand pose
Hand-collision safety task rollout
SafeHand collisionLimiting contact between neighboring hands
Video coming soon
SafeUnconstrained vs. constrainedPPO vs. a safe RL policy under a power budget
Video coming soon
Multi-AgentTwo agents, four handsBase cooperation setting
Video coming soon
Multi-AgentFour agents, one hand eachScalability setting

BibTeX

@misc{omnipiano2026,
  title  = {OmniPiano: Diverse Dexterous Piano-Playing Challenges
            for Standard, Robust, Safe, and Multi-Agent RL},
  author = {Anonymous},
  note   = {Under double-blind review},
  year   = {2026}
}